
Entende o contexto
Lê a operação, o cliente e o histórico antes de propor qualquer coisa.
Vendas, marketing, atendimento, operação, financeiro e inteligência trabalhando sobre o mesmo contexto — para sua empresa ganhar escala sem perder controle.
Sua empresa inteira. Uma operação. IA trabalhando.
Para empresas de qualquer setor que querem crescer com estrutura, controle e inteligência.
Painel ilustrativo do Sistema Centriu com sete frentes trabalhando: atendimento, comercial, operação, agentes, inteligência, conteúdo e marketing. Cada frente mostra o trabalho concluído ou o próximo passo.
Representação ilustrativa do trabalho em execução
Não é falta de ferramenta. É que cada ferramenta resolve um pedaço, e ninguém é dono do todo. O custo disso não aparece numa fatura — aparece no mês seguinte.
Sistemas que não se falam
O mesmo dado é digitado de novo — e cada cópia conta uma história diferente.
Dados duplicados
Ninguém sabe qual versão é a verdadeira na hora de decidir.
Conversas perdidas
O cliente repete o contexto a cada canal e a cada pessoa.
Tarefas espalhadas
O trabalho vive em planilhas, mensagens e na memória de alguém.
Decisões sem contexto
A escolha é feita com o recorte que estava à mão, não com o que importava.
Automações desconectadas
Cada ferramenta automatiza um pedaço e ninguém enxerga o todo.
Nenhum desses problemas se resolve comprando mais um software. Eles se resolvem quando a operação inteira passa a trabalhar sobre o mesmo contexto.
A Centriu não é uma coleção de produtos. É uma plataforma em que clientes, áreas e agentes leem e escrevem no mesmo lugar.
Cliente 360
Um contexto, não vários cadastros
Cada conversa, tarefa, campanha, cobrança e decisão fica ligada ao cliente e à operação — não a um sistema isolado.
As áreas abaixo são partes da mesma operação, não produtos separados. Elas compartilham conta, permissões e histórico.
A inteligência artificial da Centriu participa da operação: entende contexto, prepara trabalho, executa rotinas e pede aprovação quando importa.
Lê a operação, o cliente e o histórico antes de propor qualquer coisa.
Redige, organiza, calcula e deixa pronto para revisão humana.
Roda o que é repetitivo dentro dos limites definidos pela empresa.
Cruza áreas, identifica prioridade e mostra o motivo da recomendação.
O que é sensível passa por uma pessoa antes de valer. Sem exceção silenciosa.
Registra o que aconteceu e usa o resultado para melhorar a próxima decisão.
Uma plataforma, várias frentes de trabalho. Tudo no mesmo contexto, com a IA participando do que dá para acelerar.
CRM, pipeline, oportunidades, propostas, follow-up e automações.
WhatsApp, Instagram, Messenger, chat do site e e-mail no mesmo contexto.
Tarefas, responsáveis, prazos, aprovações, agenda e capacidade.
Contas, cobranças, caixa, fiscal, margem, IR, orçamento e inteligência econômica.
Planejar, produzir, aprovar, publicar e medir conteúdo e campanhas.
Painéis, alertas, previsões, recomendações e leitura executiva.
Rotinas executadas continuamente pela IA com controle e aprovação.
Diagnóstico, estratégia, transformação, acompanhamento e especialistas.
A Centriu faz sentido quando o volume aumenta e a estrutura precisa acompanhar. Não é sobre setor nem tamanho: é sobre a operação conseguir sustentar o próximo estágio.
As vendas crescem, mas o processo não acompanha.
As áreas trabalham separadas e o cliente sente.
A operação depende de pessoas específicas.
O financeiro ficou complexo e o caixa perde visibilidade.
O atendimento cresce em volume e em canais.
A IA entra sem contexto, controle ou histórico.
Se a empresa ainda não começou a crescer, a Centriu também ajuda a preparar a estrutura para o primeiro salto.
Ver a Centriu funcionandoA Centriu combina tecnologia, inteligência, método e acompanhamento. A consultoria diagnostica, desenha, implanta e acompanha — com evidências, não com apresentação.
Diagnóstico e imersão na operação
Estratégia e prioridades
Roadmap de transformação
Desenho da arquitetura operacional
Implantação conduzida
Acompanhamento com evidências
Benchmarking e leitura de mercado
Especialistas, rede e inteligência coletiva
Uma conversa para entender onde a sua operação perde tempo, dinheiro ou capacidade — e o que a Centriu faria primeiro.
problema
Centriu Axiom maintains one registry (`centriu.capabilities/1`). This registry lists every action it can call for a person. It has 37 entries now. 26 entries are live in production. These are checked against the code. 11 entries are only published as a contract. Another product tab will implement them later. Calling one of those 11 planned entries returns a specific "not implemented yet" response. It never returns a made-up number instead of real data. Each capability has one of four risk classes. These are read, compute, write, or high-impact-write. High-impact-write is for anything with an effect outside the platform. It is also for anything that cannot be undone. A special discovery function tells a specific person what they can do. It looks at their enabled modules and role. It tells them what is only planned. It also tells them what is BLOCKED with the real reason. It does not let a capability disappear without explanation. One rule never changes. Every one of the 7 live high-impact actions is refused on the ChatGPT surface. This is because ChatGPT has no screen for a person to click "Approve."
An internal AI assistant works across a company's systems. It is trustworthy only if it can say what it can and cannot touch. This must be for a specific person, right now. An assistant that refuses everything is too careful. An assistant that tries anything and fails loudly mid-task also causes problems. Both types of assistants reduce trust. People lose confidence that the assistant understands its own limits. They also lose confidence that the person using it understands its limits.
An internal AI assistant that reaches across a whole company's systems is only trustworthy if it can say, precisely, what it is and isn't authorized to touch — for a specific person, right now. An assistant that either refuses everything out of excess caution, or one that tries anything and only discovers a limit by failing loudly mid-task, both erode the same thing: confidence that the assistant understands its own boundaries as well as the person operating it does.
Every capability Axiom might call lives in one registry. This includes simple actions like "read a module's table." It also includes specific actions like "pause this ad campaign." The registry is versioned as `centriu.capabilities/1`. A human classifies each entry. It is not guessed by a model. There are four risk classes. These are read, compute, write, and high-impact-write. Read actions run freely once allowed. Compute actions use AI quota and cost. They never change business data. These are simulations or analyses. Write actions change customer data. They follow the approval policy. High-impact-write actions have an effect outside the platform. They cannot be undone. Examples are moving money, sending a message, or touching personal data. These always need clear human approval. This is true on every screen, with no exceptions.
The registry has 37 entries today. 26 are marked `disponivel`. These are confirmed against the live code. They are not just hopes. They include three general actions across modules. These are reading a table, describing its structure, and writing to it. All these follow the caller's own security rules. There are also twelve capabilities built into Axiom itself. These include listing and searching its 140 specialists. They also include running an expert panel, reading a vision analysis, and finding out what is available. Real actions inside other modules are also included. These are pausing, updating, or restarting a Maestro ad campaign. They also include replying to a support ticket by email or WhatsApp. Messaging a client through Axis is another. Building a draft governance or operational report is also included. Reading or sending through a connected Gmail account is another. The remaining 11 entries are marked `planejada`. This means they are planned. They are published in the same format for other products. These products are Gauge (for financial summaries and margin leaks), Helix (for open risks and calculated scenarios), Oracle (for project status and ICP readiness), Link (for service-volume summaries and ombudsman summaries that never include complaint text), and Flow (for governed-collection status). These products will implement them later. Calling any of these 11 today returns a specific "not implemented" response. It never returns a believable made-up number instead of real data.
A special discovery function answers the question: "what can THIS person do, here, right now?" It checks which modules are enabled for them. It checks if they have a special owner/admin role. This role bypasses checks for each module. It also checks the organization's feature flags. And it checks which screen is asking. The answer is never a silent, unexplained gap. If something exists but a person cannot reach it, it appears in a separate "blocked" list. This list includes the real reason. For example, a module might not be enabled. Or a feature flag might be turned off. If a capability just disappears, the person using it thinks "the assistant doesn't know how." But the truth might be "you haven't connected that module yet."
One rule applies to everything. A capability needs a clear flag to be offered on the ChatGPT surface. Also, every high-impact-write capability is always refused there. This is true no matter what other flags are set. This is confirmed in the Edge Function's own header comment. It is not just in a type definition. If an action needs approval on Axiom's own screen, it also needs it when the request comes from ChatGPT. ChatGPT has no screen for someone to click Approve. So, the action simply does not happen from there. There is no flag that changes this. The two AI-consuming actions offered to ChatGPT are running an expert panel and running a vision analysis. These actions use the same Edge Functions that the main app calls. Quota, feature flags, and rate limits are decided once. They are decided in one place. They are not set up again for the ChatGPT path.
37 capabilities are in one human-classified registry today. 26 are confirmed live (`disponivel`). 11 are published as a contract to be implemented later (`planejada`). These are for Gauge, Helix, Oracle, Link, and Flow.
There are four fixed risk classes. These are read, compute, write, and high-impact-write. High-impact-write always needs clear human approval on every screen, with no exceptions.
Any planned but unbuilt capability returns a specific "not implemented yet" response. It never returns a made-up number to fill the gap.
Discovery for each person returns three separate lists. These are available, planned, and blocked. The blocked list includes the specific reason. For example, a module is not enabled, or a feature is turned off. A capability never just disappears silently.
Every one of the 7 live high-impact-write capabilities is confirmed `no_chatgpt: false`. This is checked directly. None can be reached from the ChatGPT surface. This is true regardless of the general no-ChatGPT flag.
The two AI-consuming ChatGPT actions use their own Edge Functions. They do not set up quota, feature-flag, or rate-limit checks again.
A person using Axiom gets a clear, honest answer about what it can do for them. This is for right now. It is not a general list of capabilities that ignores their role and enabled modules. They also get a clear, honest answer when something is not built yet. This is better than content that looks like a real number. Every powerful action that affects things outside the platform needs the same approval. This is true no matter which screen asked for it. This means adding a new AI integration cannot secretly become an easier way to reach the same live ad budget or customer inbox.
A person working with Axiom gets a specific, honest answer about what it can do FOR THEM, right now, rather than a generic capabilities list that ignores their own role and enabled modules — and a specific, honest answer when something isn't built yet, rather than content that looks like a real number. Every powerful, external-effect action stays behind the same approval requirement no matter which surface asked for it, which means adding a new AI-facing integration can never quietly become a second, looser way to reach the same live ad budget or the same real customer inbox.
Someone asks Axiom, through ChatGPT, for a Gauge margin summary for last quarter. The capability exists as a published contract. The exact shape of the answer is already defined. But its transport is marked `nao_implementado`. Axiom does not guess a believable margin figure to be helpful. It reports that the capability is planned but not yet built. It uses the same type of response that every other unbuilt contract returns. So the person asking knows to check Gauge's own dashboard. They do not trust a number Axiom never actually calculated.
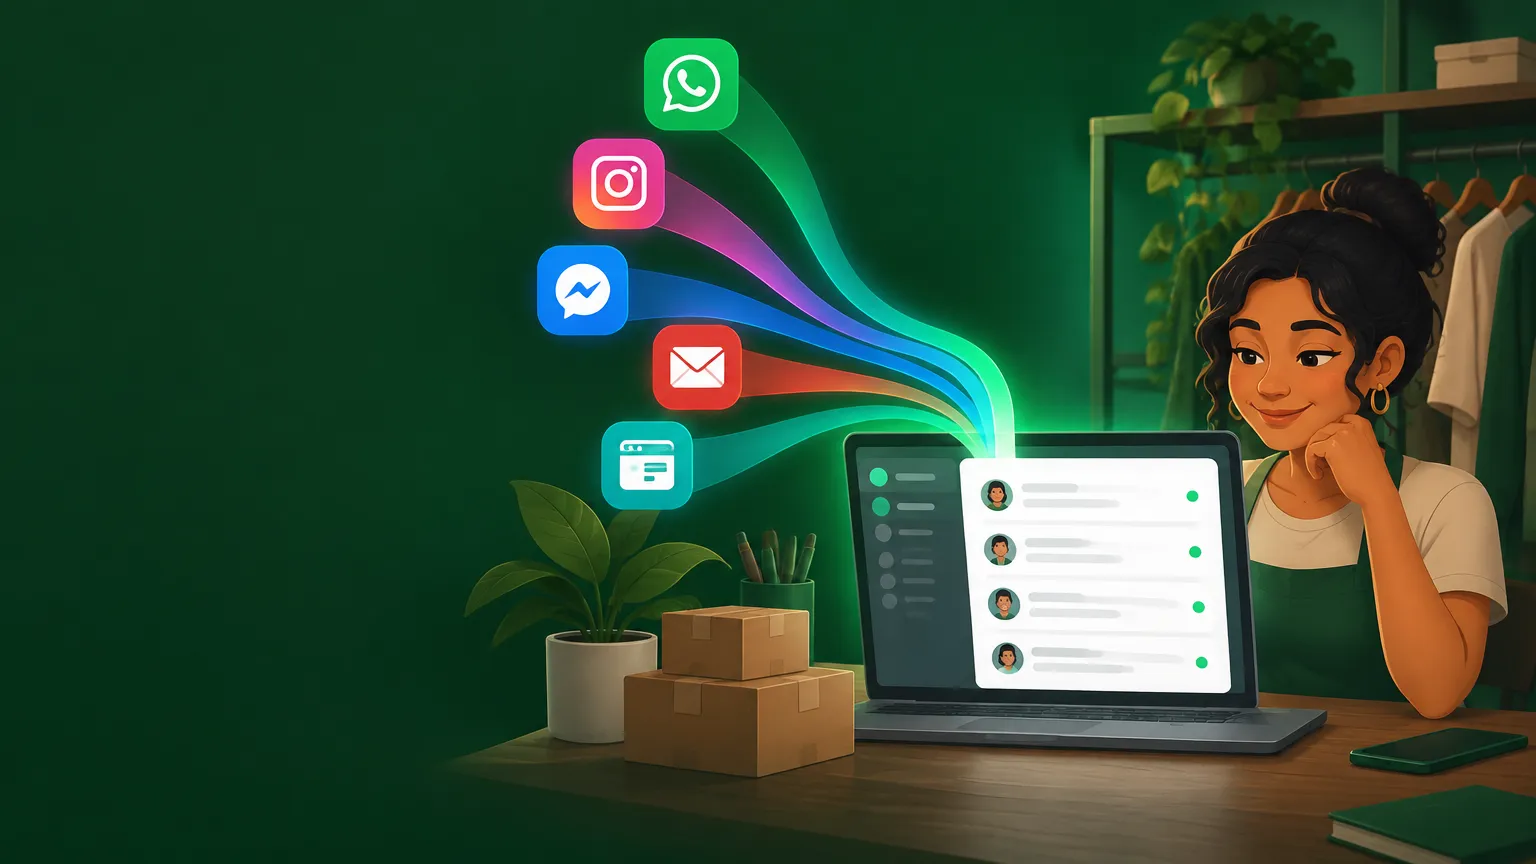
There are 37 capabilities in the registry now. 26 are confirmed live in production. 11 are published only as a contract that is not yet built. Another product team will implement these.
It returns a specific "not implemented yet" response. It never returns a made-up number instead of real data.
No. Every high-impact-write capability is refused on the ChatGPT surface. This is because that surface has no screen for a person to click Approve. There is no setting to change this.
No. It appears in a separate "blocked" list. This list includes the real reason. For example, the required module might not be enabled for that person.
No. The two AI-consuming actions it offers use the same Edge Functions that the main app uses. So, quota, feature flags, and limits are decided once, not twice.
It is sold by subscription with a published starting price. The exact current prices are on the central pricing page.
Centriu Axiom maintains one registry (`centriu.capabilities/1`). This registry lists every action it can call for a person. It has 37 entries now. 26 entries are live in production. These are checked against the code. 11 entries are only published as a contract. Another product tab will implement them later. Calling one of those 11 planned entries returns a specific "not implemented yet" response. It never returns a made-up number instead of real data. Each capability has one of four risk classes. These are read, compute, write, or high-impact-write. High-impact-write is for anything with an effect outside the platform. It is also for anything that cannot be undone. A special discovery function tells a specific person what they can do. It looks at their enabled modules and role. It tells them what is only planned. It also tells them what is BLOCKED with the real reason. It does not let a capability disappear without explanation. One rule never changes. Every one of the 7 live high-impact actions is refused on the ChatGPT surface. This is because ChatGPT has no screen for a person to click "Approve."