
Entende o contexto
Lê a operação, o cliente e o histórico antes de propor qualquer coisa.
Vendas, marketing, atendimento, operação, financeiro e inteligência trabalhando sobre o mesmo contexto — para sua empresa ganhar escala sem perder controle.
Sua empresa inteira. Uma operação. IA trabalhando.
Para empresas de qualquer setor que querem crescer com estrutura, controle e inteligência.
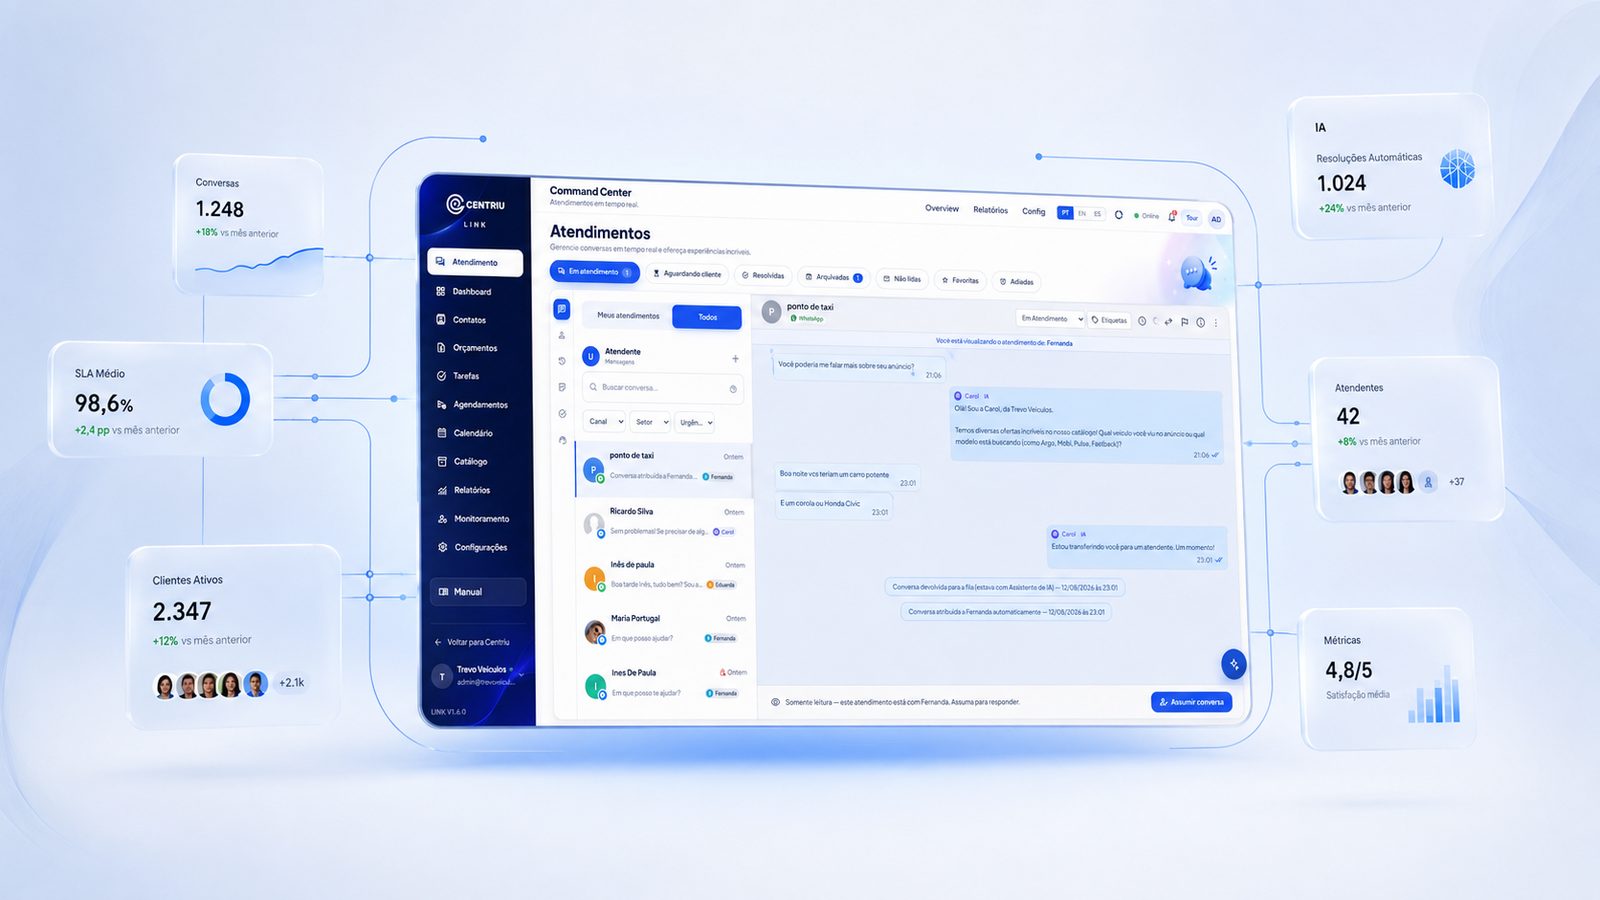
Painel ilustrativo do Sistema Centriu com sete frentes trabalhando: atendimento, comercial, operação, agentes, inteligência, conteúdo e marketing. Cada frente mostra o trabalho concluído ou o próximo passo.
Representação ilustrativa do trabalho em execução
Não é falta de ferramenta. É que cada ferramenta resolve um pedaço, e ninguém é dono do todo. O custo disso não aparece numa fatura — aparece no mês seguinte.
Sistemas que não se falam
O mesmo dado é digitado de novo — e cada cópia conta uma história diferente.
Dados duplicados
Ninguém sabe qual versão é a verdadeira na hora de decidir.
Conversas perdidas
O cliente repete o contexto a cada canal e a cada pessoa.
Tarefas espalhadas
O trabalho vive em planilhas, mensagens e na memória de alguém.
Decisões sem contexto
A escolha é feita com o recorte que estava à mão, não com o que importava.
Automações desconectadas
Cada ferramenta automatiza um pedaço e ninguém enxerga o todo.
Nenhum desses problemas se resolve comprando mais um software. Eles se resolvem quando a operação inteira passa a trabalhar sobre o mesmo contexto.
A Centriu não é uma coleção de produtos. É uma plataforma em que clientes, áreas e agentes leem e escrevem no mesmo lugar.
Cliente 360
Um contexto, não vários cadastros
Cada conversa, tarefa, campanha, cobrança e decisão fica ligada ao cliente e à operação — não a um sistema isolado.
As áreas abaixo são partes da mesma operação, não produtos separados. Elas compartilham conta, permissões e histórico.
A inteligência artificial da Centriu participa da operação: entende contexto, prepara trabalho, executa rotinas e pede aprovação quando importa.
Lê a operação, o cliente e o histórico antes de propor qualquer coisa.
Redige, organiza, calcula e deixa pronto para revisão humana.
Roda o que é repetitivo dentro dos limites definidos pela empresa.
Cruza áreas, identifica prioridade e mostra o motivo da recomendação.
O que é sensível passa por uma pessoa antes de valer. Sem exceção silenciosa.
Registra o que aconteceu e usa o resultado para melhorar a próxima decisão.
Uma plataforma, várias frentes de trabalho. Tudo no mesmo contexto, com a IA participando do que dá para acelerar.
CRM, pipeline, oportunidades, propostas, follow-up e automações.
WhatsApp, Instagram, Messenger, chat do site e e-mail no mesmo contexto.
Tarefas, responsáveis, prazos, aprovações, agenda e capacidade.
Contas, cobranças, caixa, fiscal, margem, IR, orçamento e inteligência econômica.
Planejar, produzir, aprovar, publicar e medir conteúdo e campanhas.
Painéis, alertas, previsões, recomendações e leitura executiva.
Rotinas executadas continuamente pela IA com controle e aprovação.
Diagnóstico, estratégia, transformação, acompanhamento e especialistas.
A Centriu faz sentido quando o volume aumenta e a estrutura precisa acompanhar. Não é sobre setor nem tamanho: é sobre a operação conseguir sustentar o próximo estágio.
As vendas crescem, mas o processo não acompanha.
As áreas trabalham separadas e o cliente sente.
A operação depende de pessoas específicas.
O financeiro ficou complexo e o caixa perde visibilidade.
O atendimento cresce em volume e em canais.
A IA entra sem contexto, controle ou histórico.
Se a empresa ainda não começou a crescer, a Centriu também ajuda a preparar a estrutura para o primeiro salto.
Ver a Centriu funcionandoA Centriu combina tecnologia, inteligência, método e acompanhamento. A consultoria diagnostica, desenha, implanta e acompanha — com evidências, não com apresentação.
Diagnóstico e imersão na operação
Estratégia e prioridades
Roadmap de transformação
Desenho da arquitetura operacional
Implantação conduzida
Acompanhamento com evidências
Benchmarking e leitura de mercado
Especialistas, rede e inteligência coletiva
Uma conversa para entender onde a sua operação perde tempo, dinheiro ou capacidade — e o que a Centriu faria primeiro.
problema
Before a Gauge module reaches even a controlled pilot, it goes through an internal certification audit. This audit tries to prove the module isn't ready. One audit found a critical defect in an AI chat feature. When continuing an existing conversation, the conversation's identifier arrived in the request. It was used directly to save the new question and answer. That save happened through the backend's own elevated database access. This bypasses the database's row-level security entirely. Simply sending someone else's conversation identifier — a colleague's, or a different organization's entirely — would have added a private question and its answer to that person's own chat history. The unusual part is that every individual safeguard around this feature was independently correct. The access check that ran earlier in the request genuinely verified the requester's own organization. The row-level security policy on the conversation table was itself written correctly. The gap existed structurally between those two correct layers. The identifier crossed from "what the client is asking for" into "what the server will execute" without ever being re-verified against who was actually asking. The fix re-derives the conversation using the requesting user's own restricted database access. So, the database's own row-level security decides if the conversation belongs to them. It refuses outright, rather than silently starting a new conversation, when it doesn't.
A layered security design is a good practice. This includes an access check at the API boundary and a row-level security policy at the database. Each layer catches what the other might miss. This design does not automatically guarantee that every value flowing through the system is re-verified at each layer. An identifier that a client supplies and a server later uses to perform a write can cross from "a value the requester is asking about" to "a value the server treats as already validated." This can happen without either individual layer doing anything wrong. The access check validated something real. The row-level policy is correctly written. The specific value in between was simply never checked against either.
A layered security design — an access check at the API boundary, a row-level security policy at the database — is sound practice specifically because each layer catches what the other might miss. What that design doesn't automatically guarantee is that every value flowing through the system is re-verified at each layer it passes through. An identifier that a client supplies and a server later uses to perform a write can cross from "a value the requester is asking about" to "a value the server treats as already validated" without either individual layer doing anything wrong — the access check validated something real, the row-level policy is correctly written, and the specific value in between was simply never checked against either.
This finding came from a pre-launch certification audit. This audit was built to prove a module wasn't ready. It happened before the module reached even a controlled pilot. It was not a routine test. It was a dedicated review to find real defects. It found a critical one. In the module's AI chat feature, continuing an existing conversation meant the conversation's identifier arrived directly in the request body. It was used, unmodified, in the operation that saved the new question and its answer. That save runs through the backend's own elevated database access. This mechanism lets the system perform legitimate operations regardless of row-level security. This meant the conversation table's own correctly-written ownership policy never had the chance to weigh in on that specific write at all.
The audit's own framing of the root cause is precise. It is worth stating directly. Every individual defense was working correctly. The access check that ran earlier in the request genuinely confirmed the requester belonged to the organization they claimed. The row-level security policy on the conversation table was itself correctly scoped to ownership. Neither layer was broken. The identifier itself simply crossed the boundary between "what the client is requesting" and "what the server will actually execute." It was not reclassified from an unverified claim into a checked fact at any point. The gap existed structurally between two correct layers. It was not a flaw within either one.
The fix avoids writing the ownership rule a second time by hand. This would risk the same kind of problem the original gap came from. Instead, before accepting a client-supplied conversation identifier for a continued conversation, the code re-derives that exact conversation. It uses a database connection scoped to the requesting user's own restricted access. This is the same access level the row-level security policy was always designed to govern. If that lookup succeeds and the returned conversation genuinely matches the organization, context, and original owner the request claims, the identifier is accepted. If the row-level security policy itself would not return that record for this specific user — meaning, by the database's own authoritative rule, the conversation isn't theirs — the request is refused outright with an explicit, clear error. It does not silently start a brand-new conversation in its place. The reason for that specific choice is direct. Supplying an identifier that isn't yours is not an honest typo. It does not deserve a quiet fallback. Treating it as ordinary user error would have hidden exactly the kind of attempt this fix exists to catch.
Verification was read directly from the audit's own closing report. It was done against the production database using a reverted transaction. These were genuinely realistic conditions, not a fake test environment. Three organizations and two collaborators were involved. There were systematic, deliberate attempts at cross-user and cross-organization access. 23 out of 23 attempts were correctly blocked.
A client-supplied conversation identifier is re-derived through a database connection. This connection is scoped to the requesting user's own restricted access. This happens before it is accepted, rather than trusted and used directly.
The database's own row-level security policy makes the authoritative decision. It is not a second, hand-written copy of the same rule. It decides if a given conversation belongs to the requesting user.
An explicit refusal happens whenever a supplied identifier does not genuinely belong to the requester. There is no silent fallback to a new conversation.
The specific write that adds a message to an existing conversation only proceeds. This happens once ownership has been independently re-confirmed for that exact request.
It was verified directly against the production database. A reverted transaction was used. This was done across three organizations and two collaborators. 23 out of 23 deliberate cross-user and cross-organization access attempts were correctly blocked.
It is confirmed today via direct inspection of the current edge function. The ownership re-verification block remains in place. It is unmodified since the fix.
A conversation identifier from a client request is no longer trusted on its own. It is independently re-confirmed against the requester's own restricted database access. This happens before any write occurs. It uses the same rule the database's row-level security was always designed to enforce. The specific failure mode this closes is an identifier crossing from an unverified request value into an executed database write. It does this without ever being reclassified. This is exactly the kind of gap that individual-layer testing tends not to catch. This is precisely why a dedicated, adversarial certification audit exists.
A conversation identifier arriving from a client request is no longer trusted on its own merit — it is independently re-confirmed against the requester's own restricted database access before any write occurs, using the same rule the database's row-level security was always designed to enforce. The specific failure mode this closes — an identifier crossing from an unverified request value into an executed database write without ever being reclassified — is exactly the shape of gap that individual-layer testing tends not to catch, which is precisely why a dedicated, adversarial certification audit exists.
A person continues their own AI chat conversation. They accidentally — or deliberately — send a conversation identifier. This identifier actually belongs to a colleague at a different company. This company shares the same underlying database. Before the fix, that identifier would have been accepted. The new question and its answer would have been added to the colleague's own private conversation history. After the fix, the same request is refused outright. This happens the moment the re-derivation confirms the conversation does not belong to the requester. Nothing is written. Nothing is silently redirected into a new conversation either.
The access check validated the requester's own organization. This is a genuinely different value from the specific conversation identifier later used in the write. That identifier was never independently re-verified.
The write that used the conversation identifier ran through the backend's own elevated database access. This bypasses row-level security entirely. The policy never had the chance to evaluate that specific operation.
The request is refused outright with an explicit error. The system does not silently start a new conversation in its place.
It was verified directly against the production database. A reverted transaction was used. This was done across three organizations and two collaborators. 23 out of 23 deliberate cross-user and cross-organization access attempts were correctly blocked.
No. The same audit documented three additional high-severity findings elsewhere in the module. It concluded it was ready only for internal testing at that point. This page covers only the conversation-ownership mechanism.
It is sold by subscription with a published starting price. Exact current values are on the central pricing page.
Before a Gauge module reaches even a controlled pilot, it goes through an internal certification audit. This audit tries to prove the module isn't ready. One audit found a critical defect in an AI chat feature. When continuing an existing conversation, the conversation's identifier arrived in the request. It was used directly to save the new question and answer. That save happened through the backend's own elevated database access. This bypasses the database's row-level security entirely. Simply sending someone else's conversation identifier — a colleague's, or a different organization's entirely — would have added a private question and its answer to that person's own chat history. The unusual part is that every individual safeguard around this feature was independently correct. The access check that ran earlier in the request genuinely verified the requester's own organization. The row-level security policy on the conversation table was itself written correctly. The gap existed structurally between those two correct layers. The identifier crossed from "what the client is asking for" into "what the server will execute" without ever being re-verified against who was actually asking. The fix re-derives the conversation using the requesting user's own restricted database access. So, the database's own row-level security decides if the conversation belongs to them. It refuses outright, rather than silently starting a new conversation, when it doesn't.