
Entende o contexto
Lê a operação, o cliente e o histórico antes de propor qualquer coisa.
Vendas, marketing, atendimento, operação, financeiro e inteligência trabalhando sobre o mesmo contexto — para sua empresa ganhar escala sem perder controle.
Sua empresa inteira. Uma operação. IA trabalhando.
Para empresas de qualquer setor que querem crescer com estrutura, controle e inteligência.
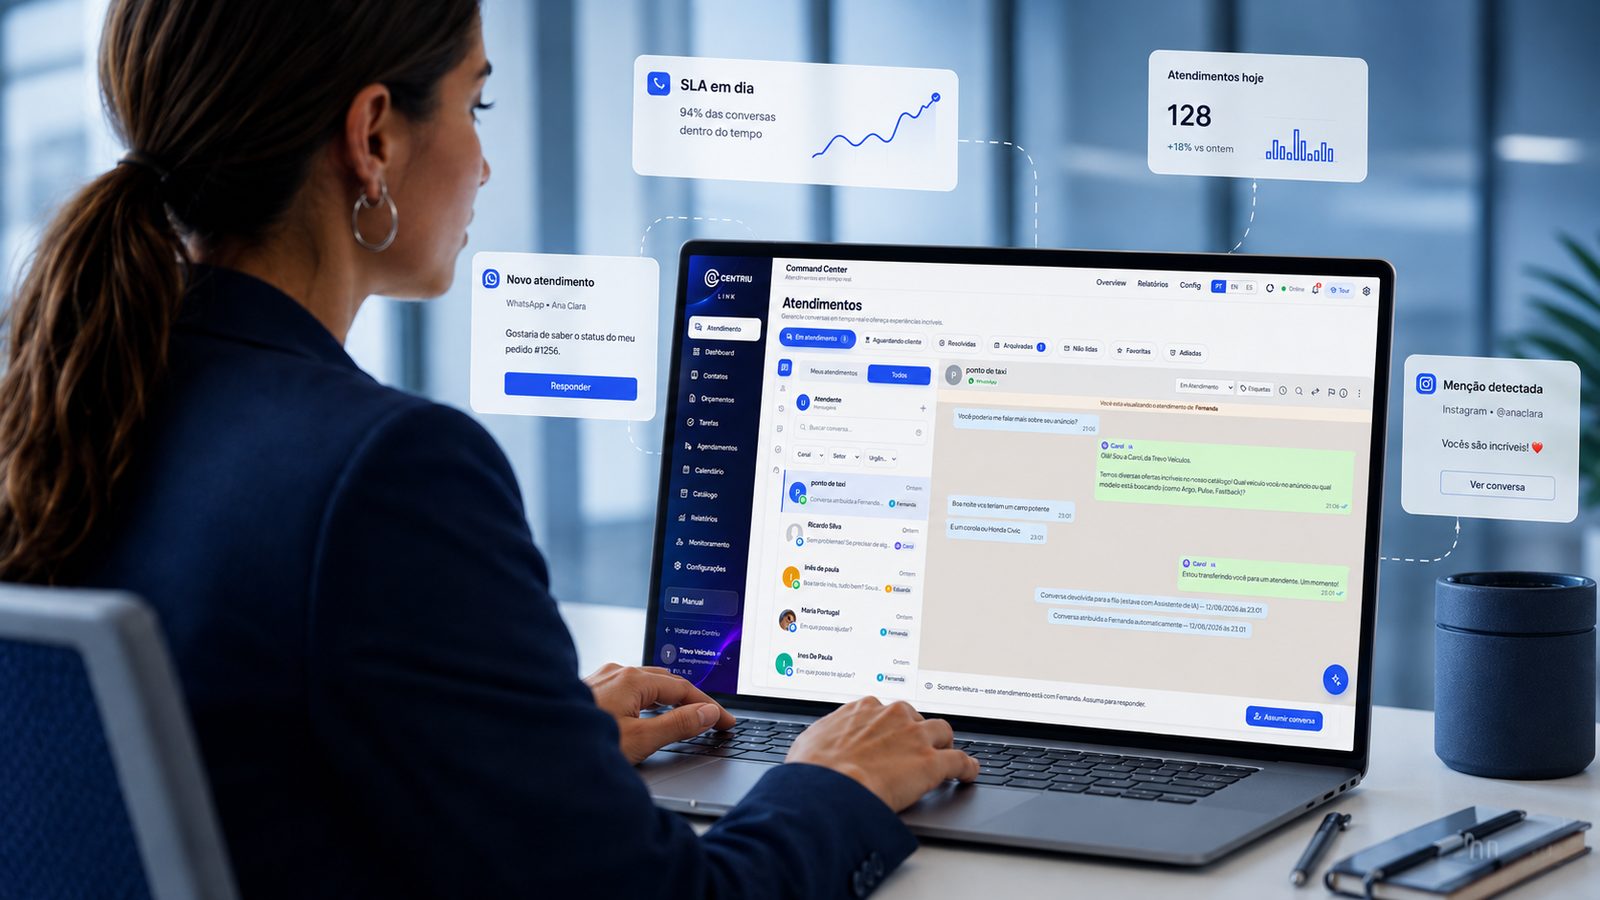
Painel ilustrativo do Sistema Centriu com sete frentes trabalhando: atendimento, comercial, operação, agentes, inteligência, conteúdo e marketing. Cada frente mostra o trabalho concluído ou o próximo passo.
Representação ilustrativa do trabalho em execução
Não é falta de ferramenta. É que cada ferramenta resolve um pedaço, e ninguém é dono do todo. O custo disso não aparece numa fatura — aparece no mês seguinte.
Sistemas que não se falam
O mesmo dado é digitado de novo — e cada cópia conta uma história diferente.
Dados duplicados
Ninguém sabe qual versão é a verdadeira na hora de decidir.
Conversas perdidas
O cliente repete o contexto a cada canal e a cada pessoa.
Tarefas espalhadas
O trabalho vive em planilhas, mensagens e na memória de alguém.
Decisões sem contexto
A escolha é feita com o recorte que estava à mão, não com o que importava.
Automações desconectadas
Cada ferramenta automatiza um pedaço e ninguém enxerga o todo.
Nenhum desses problemas se resolve comprando mais um software. Eles se resolvem quando a operação inteira passa a trabalhar sobre o mesmo contexto.
A Centriu não é uma coleção de produtos. É uma plataforma em que clientes, áreas e agentes leem e escrevem no mesmo lugar.
Cliente 360
Um contexto, não vários cadastros
Cada conversa, tarefa, campanha, cobrança e decisão fica ligada ao cliente e à operação — não a um sistema isolado.
As áreas abaixo são partes da mesma operação, não produtos separados. Elas compartilham conta, permissões e histórico.
A inteligência artificial da Centriu participa da operação: entende contexto, prepara trabalho, executa rotinas e pede aprovação quando importa.
Lê a operação, o cliente e o histórico antes de propor qualquer coisa.
Redige, organiza, calcula e deixa pronto para revisão humana.
Roda o que é repetitivo dentro dos limites definidos pela empresa.
Cruza áreas, identifica prioridade e mostra o motivo da recomendação.
O que é sensível passa por uma pessoa antes de valer. Sem exceção silenciosa.
Registra o que aconteceu e usa o resultado para melhorar a próxima decisão.
Uma plataforma, várias frentes de trabalho. Tudo no mesmo contexto, com a IA participando do que dá para acelerar.
CRM, pipeline, oportunidades, propostas, follow-up e automações.
WhatsApp, Instagram, Messenger, chat do site e e-mail no mesmo contexto.
Tarefas, responsáveis, prazos, aprovações, agenda e capacidade.
Contas, cobranças, caixa, fiscal, margem, IR, orçamento e inteligência econômica.
Planejar, produzir, aprovar, publicar e medir conteúdo e campanhas.
Painéis, alertas, previsões, recomendações e leitura executiva.
Rotinas executadas continuamente pela IA com controle e aprovação.
Diagnóstico, estratégia, transformação, acompanhamento e especialistas.
A Centriu faz sentido quando o volume aumenta e a estrutura precisa acompanhar. Não é sobre setor nem tamanho: é sobre a operação conseguir sustentar o próximo estágio.
As vendas crescem, mas o processo não acompanha.
As áreas trabalham separadas e o cliente sente.
A operação depende de pessoas específicas.
O financeiro ficou complexo e o caixa perde visibilidade.
O atendimento cresce em volume e em canais.
A IA entra sem contexto, controle ou histórico.
Se a empresa ainda não começou a crescer, a Centriu também ajuda a preparar a estrutura para o primeiro salto.
Ver a Centriu funcionandoA Centriu combina tecnologia, inteligência, método e acompanhamento. A consultoria diagnostica, desenha, implanta e acompanha — com evidências, não com apresentação.
Diagnóstico e imersão na operação
Estratégia e prioridades
Roadmap de transformação
Desenho da arquitetura operacional
Implantação conduzida
Acompanhamento com evidências
Benchmarking e leitura de mercado
Especialistas, rede e inteligência coletiva
Uma conversa para entender onde a sua operação perde tempo, dinheiro ou capacidade — e o que a Centriu faria primeiro.
problema
A real client's own words, quoted directly in the fix that closes this gap: "I sent a carousel with three images to produce, it made one and two were missing. I had to ask about four times." Image generation at Centriu ran inside the same server process handling normal web traffic, fired without waiting for a response; the underlying crash cause (a memory ceiling killing that process mid-batch) had already been fixed elsewhere, which only made the crash RARE — it did not make the platform capable of finishing a job that had already been cut short without a person manually clicking "produce missing cards." The fix adds a server-side reconciler: a lease-based claim on any production with a card still missing its image, idle for more than 12 minutes, tried fewer than 3 times, and interrupted no more than 6 hours ago. That last condition was added the same day, before the mechanism ever ran live, after every one of the 8 real incomplete productions actually found sitting in the database turned out to be 13 to 22 DAYS old — abandoned work whose brief had likely already changed, not anything a client was still waiting on.
Making a specific failure rare is real, valuable engineering. It is a completely different achievement from making a system able to recover automatically. This is for when that failure happens anyway. Rare is not the same as impossible. As long as finishing an interrupted job requires a person to notice it happened and manually intervene, the client experience during that gap is identical. This is true whether the crash occurs once a year or once a week. Work goes out incomplete. Someone has to ask, and ask again, before it's actually finished.
Making a specific failure rare is real, valuable engineering — and it is a completely different achievement from making a system able to recover automatically the next time that failure happens anyway, because rare is not the same as impossible. As long as finishing an interrupted job requires a person to notice it happened and manually intervene, the client experience during that gap is identical whether the crash occurs once a year or once a week: work goes out incomplete, and someone has to ask, and ask again, before it's actually finished.
Every piece of a multi-image production is already saved to the database. This happens the moment it finishes generating. The existing interface already calculates exactly which pieces of a given production are still missing. The parts needed to finish a job that stopped partway through had always existed. What was missing was something running that same calculation from the server side, on a schedule. It was missing something that did not wait for a person to open the item and click through it manually.
The fix adds a claim function. This function looks specifically for a production. The production must be in an in-progress or failed state. It must have at least one image genuinely missing. It must be untouched for more than 12 minutes. This time is long enough so that a production still actively generating is never mistaken for a stalled one. This active generation saves each finished piece immediately. A claimed production is marked with a lease. A lease is a timestamp. It says how long this specific attempt owns the job. If the reconciling process itself dies partway through, the lease simply expires. This is the same class of failure this whole fix exists to survive. The next scheduled cycle picks the job back up. It does not leave it locked forever by a process that no longer exists. `FOR UPDATE SKIP LOCKED` at the database level ensures two overlapping cycles never claim the same production at once. An attempt counter caps retries at three. There is a 15-minute wait built into the same lease mechanism between attempts. So, a production failing for a genuine reason cannot loop indefinitely. An example is the image provider refusing a specific prompt. It cannot burn image-generation credit chasing a failure that retrying will never fix.
The age ceiling was not part of the original design. It was added the same day. This was before the mechanism was ever switched on. It was added specifically because checking what it would have acted on first showed something the original design hadn't accounted for. All 8 real incomplete productions sitting in the database at the time were 13 to 22 DAYS old. They were not minutes or hours old. Resuming work that stale is not a rescue. It is regenerating images against a brief the client may have already changed. This happens on the client's own account. It burns real AI usage for output nobody is still waiting on. The shipped version only claims a production interrupted within the last 6 hours. Anything older is left alone entirely. This is based on the reasoning that resuming only makes sense for work someone is still genuinely expecting.
When a claimed job runs, each missing image is regenerated one at a time. This is deliberately not in parallel. Generating an entire batch simultaneously is what exhausted the server's memory limit in the first place. This started this whole chain of problems. The regeneration call itself only ever targets a card with no saved output. This makes the whole mechanism idempotent by construction. Resuming a production can never overwrite art that already exists. It can never charge twice for the same image. Every attempt writes a plain-language entry to that item's own visible history. This is true whether it fully finishes the job, partially finishes it, or gives up after the third try. It names exactly what happened. So nobody looking at a piece of finished art later has to wonder why it appeared without a person having done anything.
A scheduled server-side cycle runs every 3 minutes. It claims up to 3 interrupted productions per run. It uses a database function built specifically for this queue.
A production only qualifies if it has a genuinely missing image. It must have sat untouched for more than 12 minutes. It must have been attempted fewer than 3 times. It must have been interrupted within the last 6 hours.
A time-boxed lease reserves each claimed production for the duration of one attempt. It expires on its own if that attempt itself fails to complete. So a second dying cycle can never leave a job permanently stuck.
Missing images are regenerated one at a time per production. This is specifically to avoid the same memory pressure that caused the original interruption.
The regeneration path only ever targets a card missing its output. Resuming a production is idempotent by construction. It can never overwrite finished art or double-charge for an image.
Every attempt writes a plain-language entry to the content item's own visible history. This is true whether it is complete, partial, or abandoned after 3 tries. It names what happened and how many images were affected.
A production interrupted mid-batch now finishes on its own within minutes. This is true for the vast majority of real cases. This closes a gap where the only previous path to completion was a client asking. Sometimes they asked repeatedly. This happened before a person manually intervened.
A production interrupted mid-batch — by a deploy, a restart, or any other cause — now finishes on its own within minutes for the vast majority of real cases, closing a gap where the only previous path to completion was a client asking, sometimes repeatedly, before a person manually intervened.
A client requests a three-image carousel. The server process handling the request is interrupted. This happens after the first image finishes and saves correctly. The second and third never generate. Before this fix, that carousel simply sits incomplete. It sits until the client notices. Then they ask. Then someone opens the item to manually retry it. This is the real, quoted sequence that took roughly four requests to resolve. After the fix, the next scheduled cycle finds the same production sitting idle. This happens within minutes. It has two images missing. It regenerates exactly those two. The carousel is complete before anyone has to ask even once.
Fixing the crash's cause made it rare, not impossible. As long as no mechanism existed to finish a job that had already been interrupted, any future interruption, from any cause, still left a client with incomplete work and no automatic path to completion.
Because every real incomplete production actually found in the database when this was built was 13 to 22 days old. Resuming work that stale risks burning real image-generation usage on a brief the client may have already changed, for output nobody is still expecting.
The regeneration path only ever targets a card explicitly missing its saved output. A card that already has one is never touched. This makes resuming a production idempotent by construction.
A hard cap of three attempts is in place. There is a 15-minute wait built in between each one. After the third failed attempt, the item is marked failed with a plain-language reason. It does not retry indefinitely.
Yes — every attempt writes a plain-language entry to that content item's own visible history. This is true whether it fully finishes, partially finishes, or gives up.
It is sold by subscription with a published starting price. Exact current values are on the central pricing page.
A real client's own words, quoted directly in the fix that closes this gap: "I sent a carousel with three images to produce, it made one and two were missing. I had to ask about four times." Image generation at Centriu ran inside the same server process handling normal web traffic, fired without waiting for a response; the underlying crash cause (a memory ceiling killing that process mid-batch) had already been fixed elsewhere, which only made the crash RARE — it did not make the platform capable of finishing a job that had already been cut short without a person manually clicking "produce missing cards." The fix adds a server-side reconciler: a lease-based claim on any production with a card still missing its image, idle for more than 12 minutes, tried fewer than 3 times, and interrupted no more than 6 hours ago. That last condition was added the same day, before the mechanism ever ran live, after every one of the 8 real incomplete productions actually found sitting in the database turned out to be 13 to 22 DAYS old — abandoned work whose brief had likely already changed, not anything a client was still waiting on.