
Entende o contexto
Lê a operação, o cliente e o histórico antes de propor qualquer coisa.
Vendas, marketing, atendimento, operação, financeiro e inteligência trabalhando sobre o mesmo contexto — para sua empresa ganhar escala sem perder controle.
Sua empresa inteira. Uma operação. IA trabalhando.
Para empresas de qualquer setor que querem crescer com estrutura, controle e inteligência.
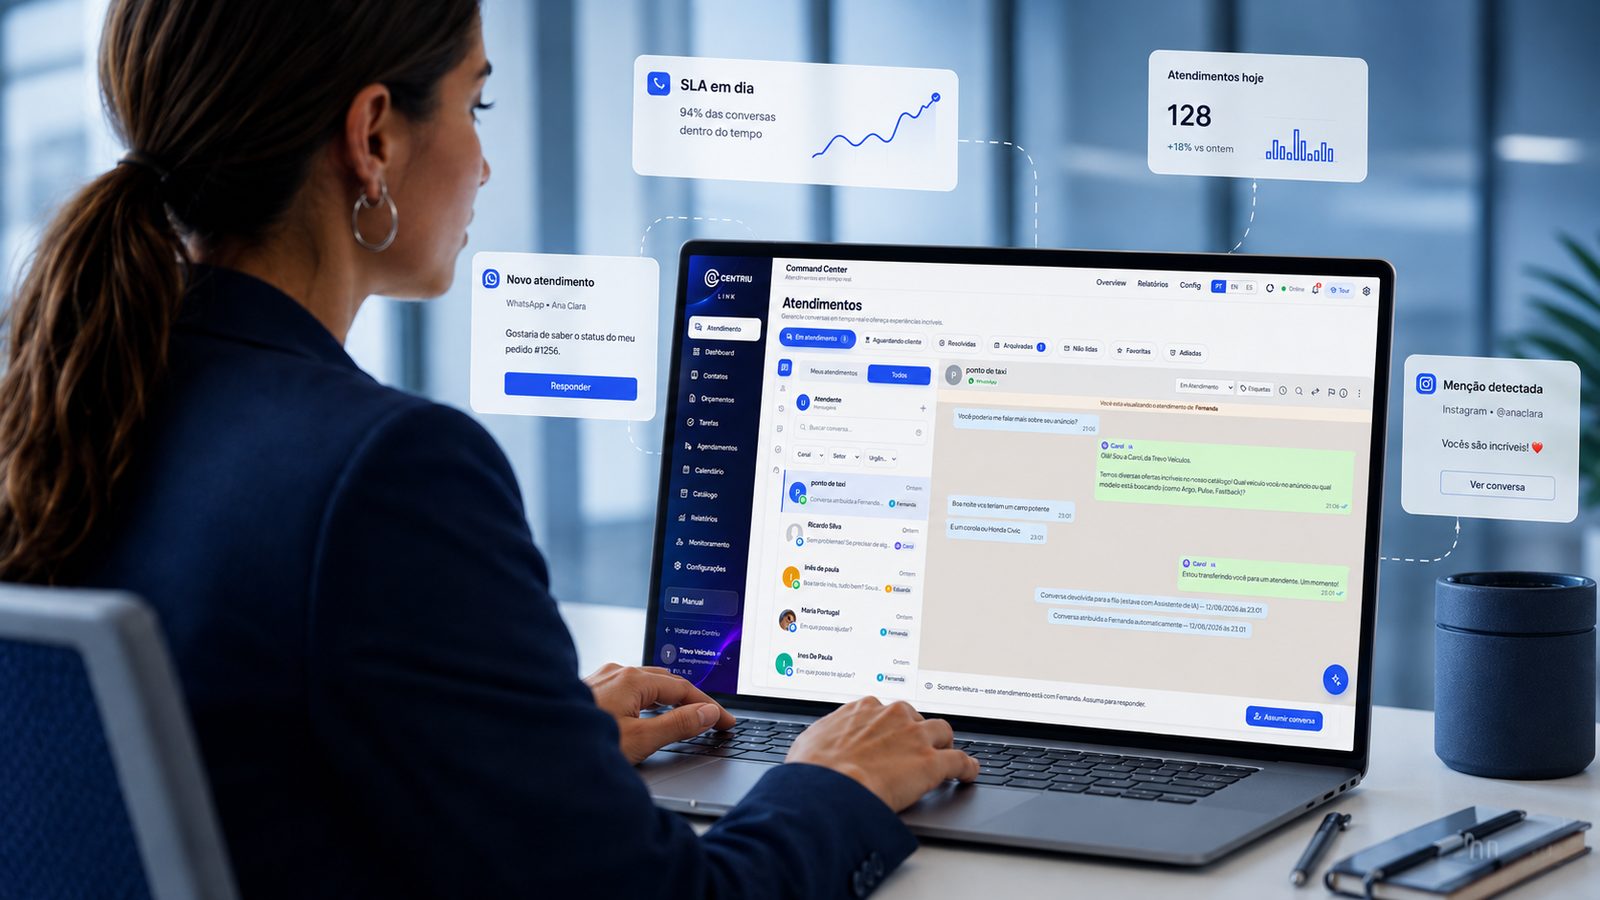
Painel ilustrativo do Sistema Centriu com sete frentes trabalhando: atendimento, comercial, operação, agentes, inteligência, conteúdo e marketing. Cada frente mostra o trabalho concluído ou o próximo passo.
Representação ilustrativa do trabalho em execução
Não é falta de ferramenta. É que cada ferramenta resolve um pedaço, e ninguém é dono do todo. O custo disso não aparece numa fatura — aparece no mês seguinte.
Sistemas que não se falam
O mesmo dado é digitado de novo — e cada cópia conta uma história diferente.
Dados duplicados
Ninguém sabe qual versão é a verdadeira na hora de decidir.
Conversas perdidas
O cliente repete o contexto a cada canal e a cada pessoa.
Tarefas espalhadas
O trabalho vive em planilhas, mensagens e na memória de alguém.
Decisões sem contexto
A escolha é feita com o recorte que estava à mão, não com o que importava.
Automações desconectadas
Cada ferramenta automatiza um pedaço e ninguém enxerga o todo.
Nenhum desses problemas se resolve comprando mais um software. Eles se resolvem quando a operação inteira passa a trabalhar sobre o mesmo contexto.
A Centriu não é uma coleção de produtos. É uma plataforma em que clientes, áreas e agentes leem e escrevem no mesmo lugar.
Cliente 360
Um contexto, não vários cadastros
Cada conversa, tarefa, campanha, cobrança e decisão fica ligada ao cliente e à operação — não a um sistema isolado.
As áreas abaixo são partes da mesma operação, não produtos separados. Elas compartilham conta, permissões e histórico.
A inteligência artificial da Centriu participa da operação: entende contexto, prepara trabalho, executa rotinas e pede aprovação quando importa.
Lê a operação, o cliente e o histórico antes de propor qualquer coisa.
Redige, organiza, calcula e deixa pronto para revisão humana.
Roda o que é repetitivo dentro dos limites definidos pela empresa.
Cruza áreas, identifica prioridade e mostra o motivo da recomendação.
O que é sensível passa por uma pessoa antes de valer. Sem exceção silenciosa.
Registra o que aconteceu e usa o resultado para melhorar a próxima decisão.
Uma plataforma, várias frentes de trabalho. Tudo no mesmo contexto, com a IA participando do que dá para acelerar.
CRM, pipeline, oportunidades, propostas, follow-up e automações.
WhatsApp, Instagram, Messenger, chat do site e e-mail no mesmo contexto.
Tarefas, responsáveis, prazos, aprovações, agenda e capacidade.
Contas, cobranças, caixa, fiscal, margem, IR, orçamento e inteligência econômica.
Planejar, produzir, aprovar, publicar e medir conteúdo e campanhas.
Painéis, alertas, previsões, recomendações e leitura executiva.
Rotinas executadas continuamente pela IA com controle e aprovação.
Diagnóstico, estratégia, transformação, acompanhamento e especialistas.
A Centriu faz sentido quando o volume aumenta e a estrutura precisa acompanhar. Não é sobre setor nem tamanho: é sobre a operação conseguir sustentar o próximo estágio.
As vendas crescem, mas o processo não acompanha.
As áreas trabalham separadas e o cliente sente.
A operação depende de pessoas específicas.
O financeiro ficou complexo e o caixa perde visibilidade.
O atendimento cresce em volume e em canais.
A IA entra sem contexto, controle ou histórico.
Se a empresa ainda não começou a crescer, a Centriu também ajuda a preparar a estrutura para o primeiro salto.
Ver a Centriu funcionandoA Centriu combina tecnologia, inteligência, método e acompanhamento. A consultoria diagnostica, desenha, implanta e acompanha — com evidências, não com apresentação.
Diagnóstico e imersão na operação
Estratégia e prioridades
Roadmap de transformação
Desenho da arquitetura operacional
Implantação conduzida
Acompanhamento com evidências
Benchmarking e leitura de mercado
Especialistas, rede e inteligência coletiva
Uma conversa para entender onde a sua operação perde tempo, dinheiro ou capacidade — e o que a Centriu faria primeiro.
problema
A team that spends weeks inside its own positioning document loses the ability to see the brand the way a stranger encountering it for the first time actually would. Centriu Vesper's perception simulator produces that outside view mechanically: it detects a brand archetype and an ideal-customer type from keyword patterns in the same positioning, territory and style text the team already declared, then builds a structured first-impression read — an emotional reading, a rational reading, an implicit judgment, an engagement estimate, and a short list of quick wins. This is a deterministic, rule-based heuristic pattern-matching on declared text, not a real customer survey, a focus group, or an AI-model-generated persona, and it guarantees no outcome — its engagement estimate is a heuristic over the declared text, and the tool's own interface labels every result with an explicit confidence level tied to how much branding and strategy data actually exists to pattern-match against.
By the time a positioning statement, a color palette and a message house exist, the people who built them have spent so long inside the decisions that they can no longer see the brand the way someone encountering it for the first time actually would. Every choice looks justified because they remember the reasoning behind it — the reasoning a first-time visitor never gets to see. That blind spot is structural, not a matter of skill: the closer someone is to a decision, the harder it becomes to judge how that decision reads cold, without any of the internal context that made it feel obvious.
By the time a positioning statement, a color palette and a message house exist, the people who built them have spent so long inside the decisions that they can no longer see the brand the way someone encountering it for the first time actually would. Every choice looks justified because they remember the reasoning behind it — the reasoning a first-time visitor never gets to see. That blind spot is structural, not a matter of skill: the closer someone is to a decision, the harder it becomes to judge how that decision reads cold, without any of the internal context that made it feel obvious.
The simulator reads the same declared inputs already sitting in the project — brand style, sensation, sophistication level, the desired and undesired perception statements, color and font counts, positioning statement, territory, central promise, the "common enemy" concept, and ideal-customer description — and runs two independent pattern-detection passes over the text. The first detects one of seven brand archetypes (premium, performance, institutional, human, tech, bold or neutral) by matching keyword patterns against the positioning statement, territory, brand style and segment description — "premium," "luxo," "sofisticado" and similar terms point toward the premium archetype; "resultado," "roi," "conversão" toward performance, and so on. The second, independently, detects one of six ideal-customer types (premium, B2B, mass-market, institutional, young or neutral) from the same kind of keyword pattern in the customer-profile text. A numeric "perception strength" score, built from a weighted checklist of which fields are actually filled in, then drives an explicit confidence label — low, medium or high — attached to the entire simulated read. From there, the simulator produces a first impression (a plain-language reading, plus separate clarity and impact levels), an emotional reading (the predominant emotions the material is likely to evoke, and what strengthens or weakens that read), a rational reading (the promise a stranger would probably perceive, and how clearly), an implicit judgment (the almost-instant, often-unstated conclusion a viewer forms and why), a read of which specific attributes the brand is likely to be perceived AS versus which desired attributes are probably missing, an engagement estimate, a conversion-effect read (favors, neutral or limits), a short list of specific quick wins, and an overall verdict naming the current probable perception, the main gap, the main risk and the main opportunity. Every one of these outputs is generated by fixed, deterministic logic keyed to the detected archetype and customer type and the completeness of the underlying data — never by a generative AI model, and never by actual customer input. The interface itself gates the whole feature behind a minimum data-completeness threshold and keeps the confidence label permanently visible on the result, the same honesty pattern this pillar has already documented elsewhere in Vesper's own product.
A deterministic, keyword-pattern archetype detector — seven possible archetypes (premium, performance, institutional, human, tech, bold, neutral) — matched against the brand's own declared positioning, territory, style and segment text.
An independent, separate keyword-pattern detector for one of six ideal-customer types, run against the declared customer-profile text.
A structured simulated read covering first impression, emotional reading, rational reading, implicit judgment, perceived-versus-missing attributes, an engagement estimate, a conversion-effect read, and a short quick-win list.
An overall verdict naming the current probable perception, the main gap against the declared intention, the main risk and the main opportunity.
A numeric perception-strength score, built from a weighted checklist of which branding and strategy fields are actually filled in, driving an explicit low/medium/high confidence label.
The feature only renders once a minimum data-completeness threshold is met, and the confidence label stays permanently visible on the result rather than being tucked away.
A structurally separate engine, in a separate source file, from the brand-strategy coherence scorer — this one produces a simulated outside view; the other audits whether the brand's own declared elements agree with each other.
Zero calls to a generative AI model or to any real customer, panel or survey data anywhere in the simulation logic — the entire read is derived from fixed rules over the team's own declared text.
A team gets a fast, repeatable first pass at how its own material probably reads to a stranger, before spending on real user research or, worse, finding out from actual launch feedback. A gap between internal intent and probable outside reading gets a specific name — a missing sensation field, an unaddressed archetype mismatch — instead of staying an unexamined assumption that everyone privately hopes is not a problem.
A team gets a fast, repeatable first pass at how its own material probably reads to a stranger, before spending on real user research or, worse, finding out from actual launch feedback. A gap between internal intent and probable outside reading gets a specific name — a missing sensation field, an unaddressed archetype mismatch — instead of staying an unexamined assumption that everyone privately hopes is not a problem.
A project's positioning statement leans heavily on words like "inovador," "tecnologia" and "digital," and the brand style is declared as "moderno." The archetype detector matches this pattern to "tech" rather than the "human" archetype the team had informally been describing the brand as internally. The ideal-customer text reads as B2B — references to "empresa," "gestor," "decisor."
The simulated first impression reads as clear but somewhat cold: professionalism registers, but the emotional reading shows a weak "human" signal, with the weakening factor named explicitly as the absence of any warmth-oriented language in the declared sensation field. The verdict names the main gap plainly: the team's internal sense of the brand as approachable is not showing up in what the declared material would probably communicate to a stranger. A quick win is surfaced: add a specific "sensation" field describing the human, approachable quality the team wants readers to feel, since that field is currently empty and is exactly the kind of signal the detector is built to pick up. The whole result carries a "media" confidence label, because several optional fields — critical errors, application guidelines — remain unfilled.
No — it is a deterministic, keyword-pattern simulation over the team's own declared branding and strategy text. No real customer, panel or survey data is involved.
No — the archetype and customer-type detection and every simulated output are produced by fixed, rule-based logic, not a generative AI model.
Not from real customer behavior — its engagement estimate and conversion-effect read are heuristics over the declared material, and no real-world outcome is guaranteed.
One of seven categories — premium, performance, institutional, human, tech, bold or neutral — detected by matching keyword patterns in the brand's own declared positioning, territory and style text.
Because the simulation is only as informative as the underlying declared data. A numeric perception-strength score, based on which fields are actually filled in, drives an explicit low, medium or high confidence label shown with every result.
No — that is a separate engine, in a separate file, that audits whether the brand's own declared elements agree with each other. This one simulates how a first-time outside viewer would probably read the same material.
It is sold by subscription with a published starting price — exact current values are on the central pricing page.
A team that spends weeks inside its own positioning document loses the ability to see the brand the way a stranger encountering it for the first time actually would. Centriu Vesper's perception simulator produces that outside view mechanically: it detects a brand archetype and an ideal-customer type from keyword patterns in the same positioning, territory and style text the team already declared, then builds a structured first-impression read — an emotional reading, a rational reading, an implicit judgment, an engagement estimate, and a short list of quick wins. This is a deterministic, rule-based heuristic pattern-matching on declared text, not a real customer survey, a focus group, or an AI-model-generated persona, and it guarantees no outcome — its engagement estimate is a heuristic over the declared text, and the tool's own interface labels every result with an explicit confidence level tied to how much branding and strategy data actually exists to pattern-match against.