
Entende o contexto
Lê a operação, o cliente e o histórico antes de propor qualquer coisa.
Vendas, marketing, atendimento, operação, financeiro e inteligência trabalhando sobre o mesmo contexto — para sua empresa ganhar escala sem perder controle.
Sua empresa inteira. Uma operação. IA trabalhando.
Para empresas de qualquer setor que querem crescer com estrutura, controle e inteligência.
Painel ilustrativo do Sistema Centriu com sete frentes trabalhando: atendimento, comercial, operação, agentes, inteligência, conteúdo e marketing. Cada frente mostra o trabalho concluído ou o próximo passo.
Representação ilustrativa do trabalho em execução
Não é falta de ferramenta. É que cada ferramenta resolve um pedaço, e ninguém é dono do todo. O custo disso não aparece numa fatura — aparece no mês seguinte.
Sistemas que não se falam
O mesmo dado é digitado de novo — e cada cópia conta uma história diferente.
Dados duplicados
Ninguém sabe qual versão é a verdadeira na hora de decidir.
Conversas perdidas
O cliente repete o contexto a cada canal e a cada pessoa.
Tarefas espalhadas
O trabalho vive em planilhas, mensagens e na memória de alguém.
Decisões sem contexto
A escolha é feita com o recorte que estava à mão, não com o que importava.
Automações desconectadas
Cada ferramenta automatiza um pedaço e ninguém enxerga o todo.
Nenhum desses problemas se resolve comprando mais um software. Eles se resolvem quando a operação inteira passa a trabalhar sobre o mesmo contexto.
A Centriu não é uma coleção de produtos. É uma plataforma em que clientes, áreas e agentes leem e escrevem no mesmo lugar.
Cliente 360
Um contexto, não vários cadastros
Cada conversa, tarefa, campanha, cobrança e decisão fica ligada ao cliente e à operação — não a um sistema isolado.
As áreas abaixo são partes da mesma operação, não produtos separados. Elas compartilham conta, permissões e histórico.
A inteligência artificial da Centriu participa da operação: entende contexto, prepara trabalho, executa rotinas e pede aprovação quando importa.
Lê a operação, o cliente e o histórico antes de propor qualquer coisa.
Redige, organiza, calcula e deixa pronto para revisão humana.
Roda o que é repetitivo dentro dos limites definidos pela empresa.
Cruza áreas, identifica prioridade e mostra o motivo da recomendação.
O que é sensível passa por uma pessoa antes de valer. Sem exceção silenciosa.
Registra o que aconteceu e usa o resultado para melhorar a próxima decisão.
Uma plataforma, várias frentes de trabalho. Tudo no mesmo contexto, com a IA participando do que dá para acelerar.
CRM, pipeline, oportunidades, propostas, follow-up e automações.
WhatsApp, Instagram, Messenger, chat do site e e-mail no mesmo contexto.
Tarefas, responsáveis, prazos, aprovações, agenda e capacidade.
Contas, cobranças, caixa, fiscal, margem, IR, orçamento e inteligência econômica.
Planejar, produzir, aprovar, publicar e medir conteúdo e campanhas.
Painéis, alertas, previsões, recomendações e leitura executiva.
Rotinas executadas continuamente pela IA com controle e aprovação.
Diagnóstico, estratégia, transformação, acompanhamento e especialistas.
A Centriu faz sentido quando o volume aumenta e a estrutura precisa acompanhar. Não é sobre setor nem tamanho: é sobre a operação conseguir sustentar o próximo estágio.
As vendas crescem, mas o processo não acompanha.
As áreas trabalham separadas e o cliente sente.
A operação depende de pessoas específicas.
O financeiro ficou complexo e o caixa perde visibilidade.
O atendimento cresce em volume e em canais.
A IA entra sem contexto, controle ou histórico.
Se a empresa ainda não começou a crescer, a Centriu também ajuda a preparar a estrutura para o primeiro salto.
Ver a Centriu funcionandoA Centriu combina tecnologia, inteligência, método e acompanhamento. A consultoria diagnostica, desenha, implanta e acompanha — com evidências, não com apresentação.
Diagnóstico e imersão na operação
Estratégia e prioridades
Roadmap de transformação
Desenho da arquitetura operacional
Implantação conduzida
Acompanhamento com evidências
Benchmarking e leitura de mercado
Especialistas, rede e inteligência coletiva
Uma conversa para entender onde a sua operação perde tempo, dinheiro ou capacidade — e o que a Centriu faria primeiro.
problema
Every pattern Centriu Run's Memory Engine detects carries a confidence score from 28 to 96. This score is computed by one fixed formula. The formula is 22 base points plus 12 per occurrence, 11 per distinct context, 10 per positive signal, plus a recency factor. It is never computed by a model call. So, the same inputs always produce the same number. That score sorts each memory into one of four lifecycle stages. It uses hard numeric gates. The stages are: "em observação" by default, "recorrente" at two or more occurrences, "consolidado" at four or more occurrences with at least 72% confidence, and "reutilizável." This last stage is reached only once occurrences, contexts, confidence and a positive signal all clear their own threshold at the same time. Nothing here is stored as a finished verdict. The whole set of memories is rebuilt from live task, mind-map, decision and action data every time it's read. So, a memory's confidence can rise or fall between two reads as the underlying operation actually changes.
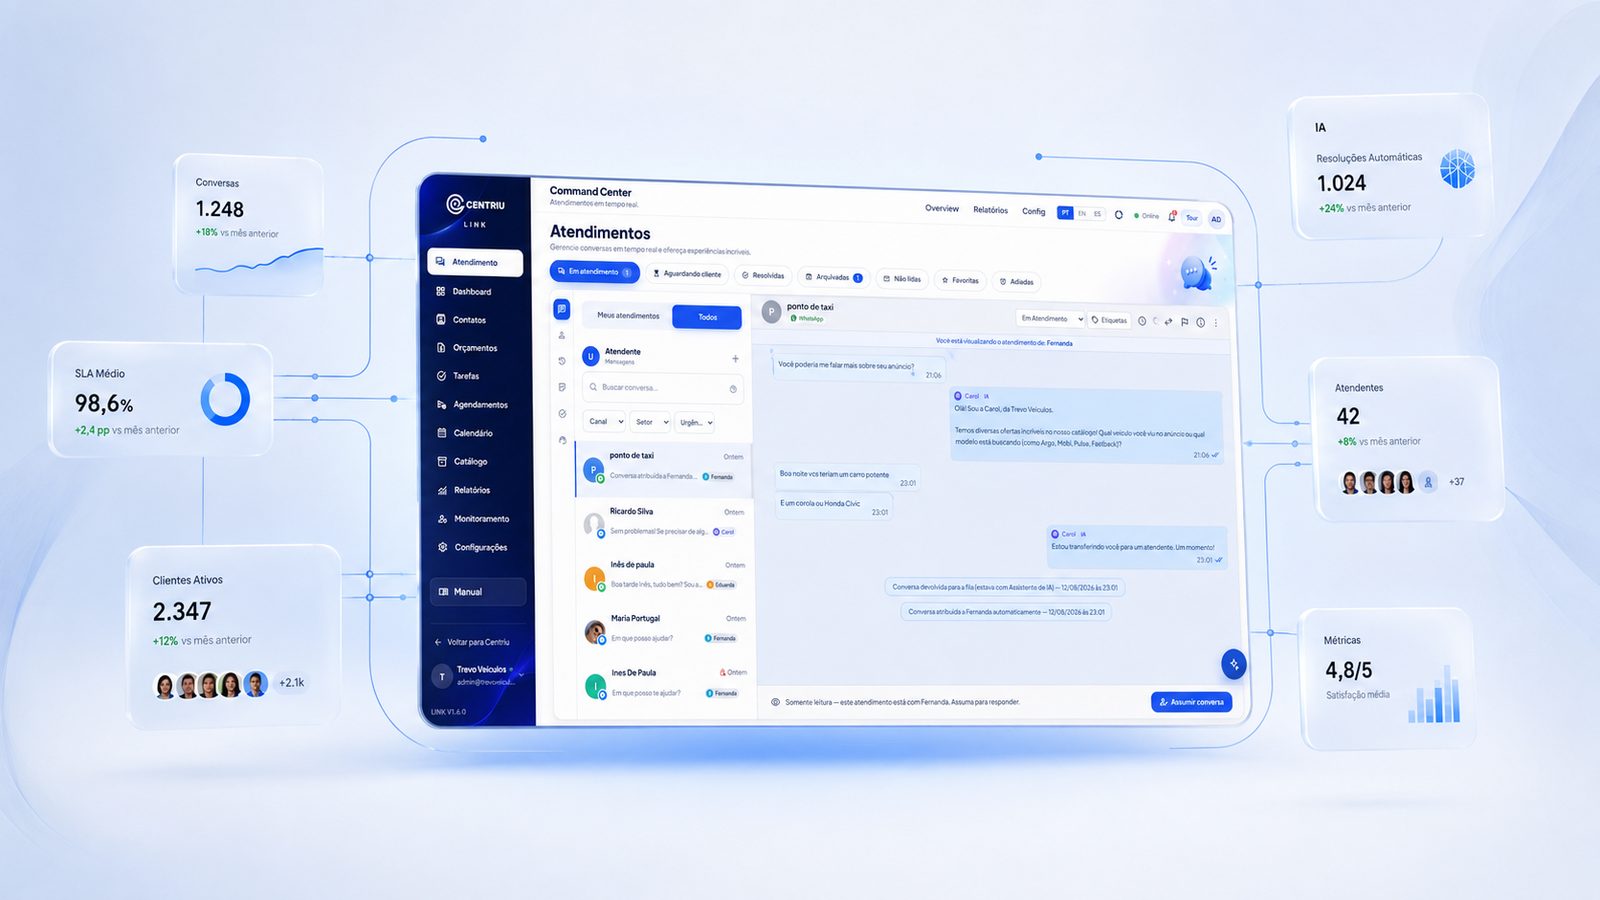
A system that flags a pattern without saying how confident it actually is puts the reader in the position of deciding, on faith, whether a two-time coincidence and a five-time habit deserve the same weight. And if that confidence came from a model's read of the situation, asking again tomorrow — same data, same question — isn't guaranteed to produce the same number, which makes the score itself something to double-check rather than something to act on.
A system that flags a pattern without saying how confident it actually is puts the reader in the position of deciding, on faith, whether a two-time coincidence and a five-time habit deserve the same weight. And if that confidence came from a model's read of the situation, asking again tomorrow — same data, same question — isn't guaranteed to produce the same number, which makes the score itself something to double-check rather than something to act on.
Every memory's confidence starts at a base of 22. It adds a fixed amount for each input that strengthens it. This is 12 points for every occurrence recorded. It is 11 for every distinct context the pattern has shown up in. It is 10 for every positive signal attached to it. Plus, there is a recency factor that varies by rule. The result is capped to a floor of 28 and a ceiling of 96. No memory, however thin, scores below 28. And none, however strong, is presented as absolute certainty. That number then sorts into three plain bands. Below 58 is low confidence. 58 to 77 is medium. 78 and above is high.
The same numbers also decide which of four lifecycle stages a memory sits in. A brand-new pattern starts "em observação." It becomes "recorrente" once it has at least two occurrences. No confidence minimum is required yet. The point of this stage is just to acknowledge that something has repeated. It becomes "consolidado" once it has at least four occurrences AND at least 72% confidence. Both conditions must be met, not just one. It only reaches "reutilizável." This is the stage where other screens are allowed to actively surface it as a working recommendation. This happens once four conditions are true at the same time. These are: at least five occurrences, at least two distinct contexts, at least 80% confidence, and at least one recorded positive signal.
Nothing here is stored as a finished conclusion. The full list of memories is not read from a saved "memories" table. It is rebuilt from scratch every time the engine runs. It is rebuilt directly from the same live task list, mind maps, decision history, and prepared actions the rest of Run already uses. Only the raw events themselves are saved. How often each memory has actually been reused elsewhere is also saved. The derived confidence and stage are always a fresh calculation against current data. This means a memory that hit "reutilizável" last week can genuinely drop back down. This happens if the underlying signals that earned it change. For example, a completed overdue task, a decision that resolved, or a mind map that got real execution behind it.
One fixed formula for every memory: 22 base points plus 12 per occurrence, 11 per distinct context, 10 per positive signal, plus a recency factor — clamped between 28 and 96.
Three plain confidence bands: below 58 low, 58–77 medium, 78 and above high — the same cutoffs applied to every memory, every time.
Four lifecycle stages with hard, simultaneous numeric gates — "reutilizável" status requires occurrences, contexts, confidence and a positive signal to all clear their own threshold at once, not any one of them alone.
No stored "memories" table — the entire list is rebuilt live from real task, mind-map, decision and action data on every read, never frozen into a saved verdict.
A separate usage counter tracks how many times each memory has actually been surfaced elsewhere. It is shown alongside the confidence score itself. It is never mixed into the confidence score itself.
No manual override — nothing in the interface lets a user directly set or edit a memory's confidence or stage; both are always the output of the same formula.
Two patterns with different track records stop looking the same at a glance. The stage and the number both say, in the same fixed language every time, how much weight this specific memory has actually earned. And because the whole list recomputes from live data instead of freezing a past verdict, a memory that stops being true stops being presented as confidently as it once was. This happens without anyone having to go in and manually retire it.
Two patterns with different track records stop looking the same at a glance. The stage and the number both say, in the same fixed language every time, how much weight this specific memory has actually earned. And because the whole list recomputes from live data instead of freezing a past verdict, a memory that stops being true stops being presented as confidently as it once was. This happens without anyone having to go in and manually retire it.
A recurring-overload pattern for one team first crosses the "recorrente" gate. This happens the moment it logs its second overdue-heavy week. Its confidence is in the high 40s. There are no promises yet, just an acknowledged repeat. Three more overdue-heavy weeks later, the same pattern's confidence has climbed past 80. This is now with occurrences across more than one context. It also has a couple of resolved incidents counted as positive signals. Its stage has advanced to "reutilizável." This is the exact point at which it starts actively surfacing as a note inside other screens. It no longer sits quietly in the Memory Engine's own list.
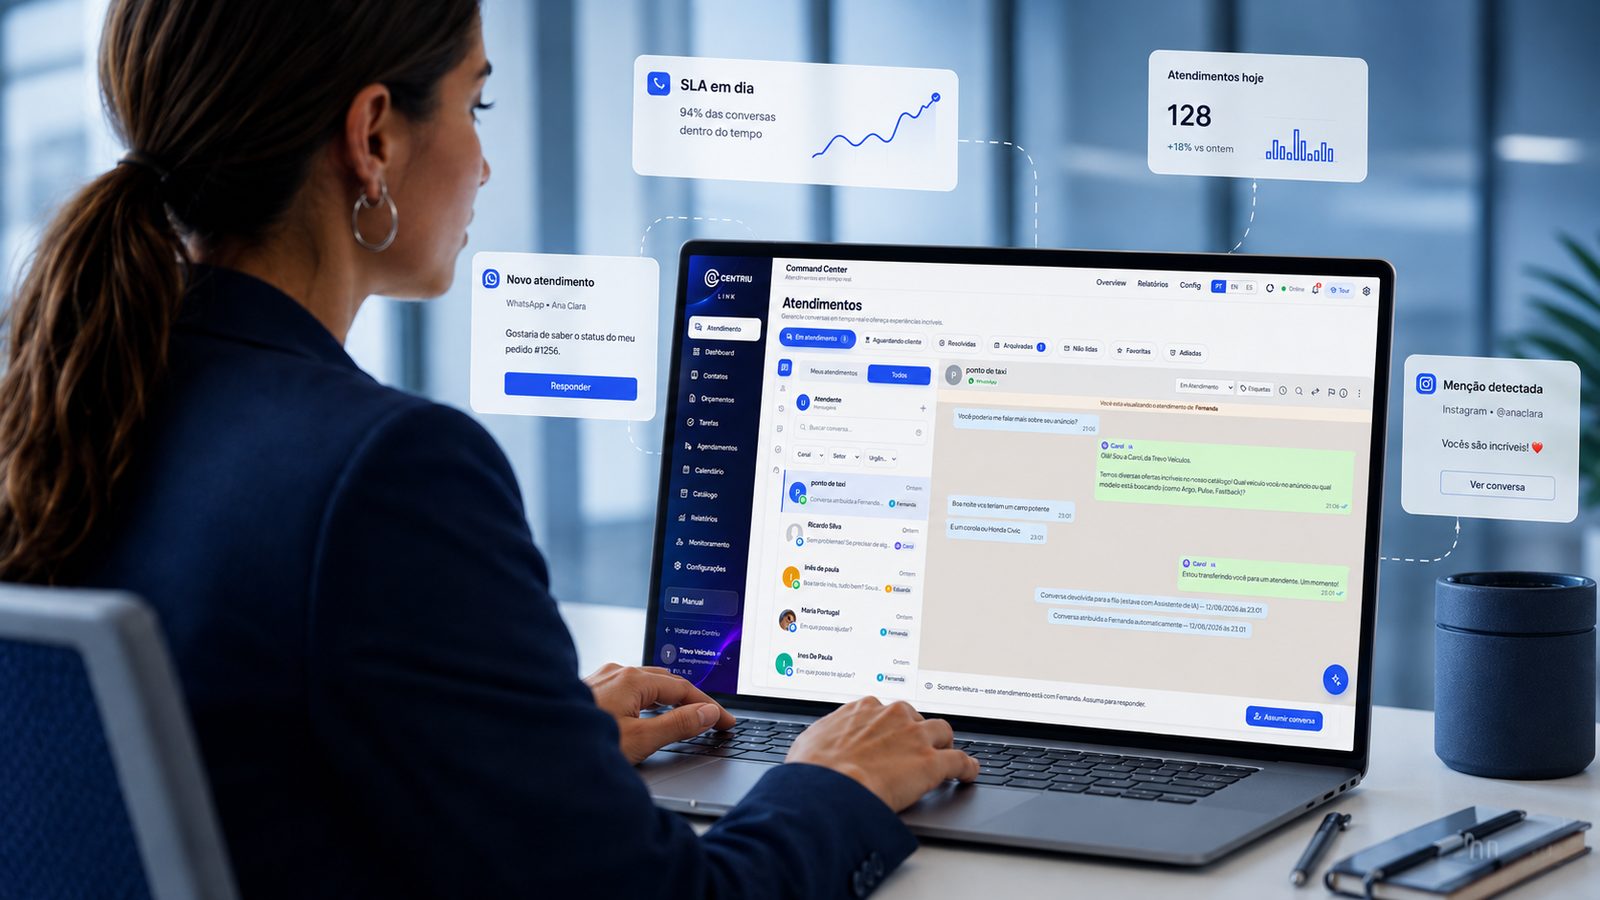
22 base points, plus 12 per occurrence, 11 per distinct context, and 10 per positive signal, plus a recency factor — the total is capped between 28 and 96.
Yes — since the whole list recomputes from live data every time, a memory that no longer meets a stage's numeric gate is no longer shown at that stage.
Four conditions at once: at least five occurrences, at least two distinct contexts, at least 80% confidence, and at least one positive signal — not any one of those alone.
No — there is no override; confidence and stage are always computed by the same formula and gates for every memory.
No — usage is tracked and shown as a separate figure, never folded into the confidence formula itself.
It is sold by subscription with a published starting price — exact current values are on the central pricing page.
Every pattern Centriu Run's Memory Engine detects carries a confidence score from 28 to 96. This score is computed by one fixed formula. The formula is 22 base points plus 12 per occurrence, 11 per distinct context, 10 per positive signal, plus a recency factor. It is never computed by a model call. So, the same inputs always produce the same number. That score sorts each memory into one of four lifecycle stages. It uses hard numeric gates. The stages are: "em observação" by default, "recorrente" at two or more occurrences, "consolidado" at four or more occurrences with at least 72% confidence, and "reutilizável." This last stage is reached only once occurrences, contexts, confidence and a positive signal all clear their own threshold at the same time. Nothing here is stored as a finished verdict. The whole set of memories is rebuilt from live task, mind-map, decision and action data every time it's read. So, a memory's confidence can rise or fall between two reads as the underlying operation actually changes.